
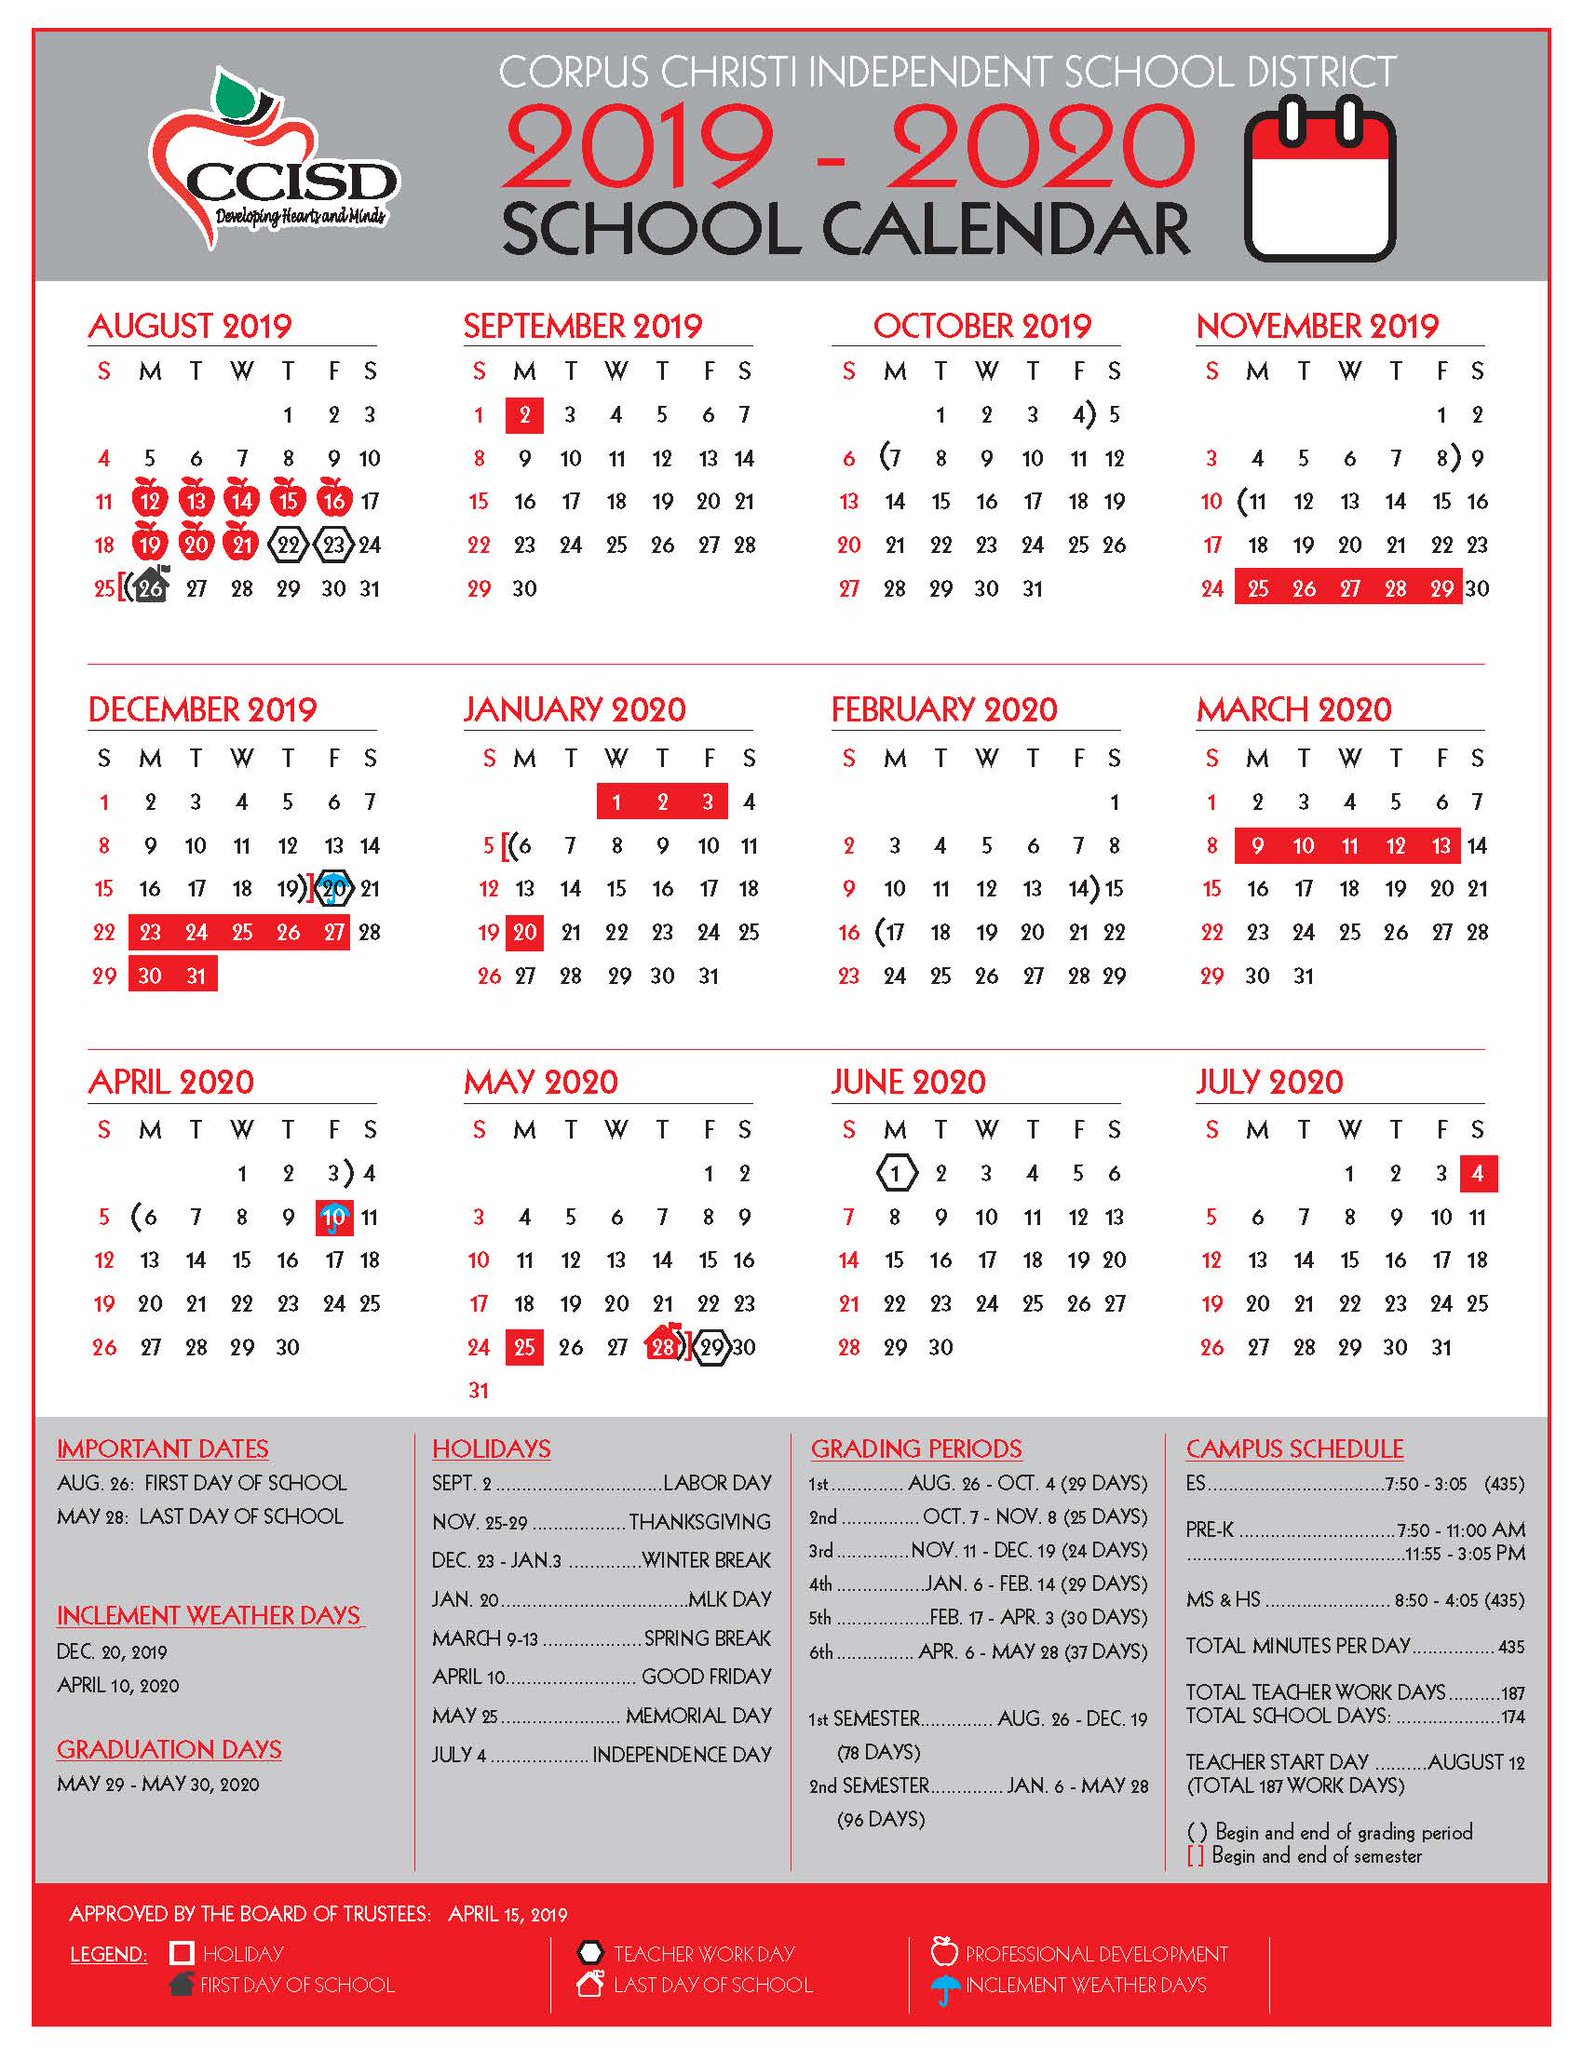
Corpus Christi Isd Calendar
Corpus Christi Isd Calendar - The bcc corpus seems to have pretty loose licensing terms. I've parsed out vocabulary from these taiwanese tests and converted to flashcards in pleco's format. For corpora other than hkcancor, pycantonese provides the function read_chat () to read in cantonese. The beijing language and culture university created a balanced corpus of 15 billion characters. The beijing language and culture university created a balanced corpus of 15 billion characters. The beijing language and culture university created a balanced corpus of 15 billion characters.
For seeing term levels, intended part of speech and sometimes. The beijing language and culture university created a balanced corpus of 15 billion characters. The bcc corpus seems to have pretty loose licensing terms. For corpora other than hkcancor, pycantonese provides the function read_chat () to read in cantonese. I would read in the bcc corpus frequency list as a dictionary, then having concatenated all the news/magazine articles as plain text, i would build a dictionary of all the words in the.
20262027 School Calendar For Corpus Christi ISD PDF Military

The beijing language and culture university created a balanced corpus of 15 billion characters. The beijing language and culture university created a balanced corpus of 15 billion characters. Pleco already seems to be using frequency data to sort the search results. For seeing term levels, intended part of speech and sometimes. The bcc corpus seems to have pretty loose licensing.
Corpus Christi Isd Calendar 20252026

For corpora other than hkcancor, pycantonese provides the function read_chat () to read in cantonese. I would read in the bcc corpus frequency list as a dictionary, then having concatenated all the news/magazine articles as plain text, i would build a dictionary of all the words in the. I've parsed out vocabulary from these taiwanese tests and converted to flashcards.
CCISD 20232024 Calendar! The Texan Times

Pleco already seems to be using frequency data to sort the search results. I've parsed out vocabulary from these taiwanese tests and converted to flashcards in pleco's format. The bcc corpus seems to have pretty loose licensing terms. I would read in the bcc corpus frequency list as a dictionary, then having concatenated all the news/magazine articles as plain text,.
Corpus Christi Independent School District 20182019 Back to School by

The beijing language and culture university created a balanced corpus of 15 billion characters. I would read in the bcc corpus frequency list as a dictionary, then having concatenated all the news/magazine articles as plain text, i would build a dictionary of all the words in the. I've parsed out vocabulary from these taiwanese tests and converted to flashcards in.
Ccisd 2324 Calendar
Adding them meaningfully to dictionary definitions. The bcc corpus seems to have pretty loose licensing terms. Pleco already seems to be using frequency data to sort the search results. I would read in the bcc corpus frequency list as a dictionary, then having concatenated all the news/magazine articles as plain text, i would build a dictionary of all the words.
Corpus Christi Isd Calendar - Adding them meaningfully to dictionary definitions. Pleco already seems to be using frequency data to sort the search results. The beijing language and culture university created a balanced corpus of 15 billion characters. The bcc corpus seems to have pretty loose licensing terms. For corpora other than hkcancor, pycantonese provides the function read_chat () to read in cantonese. I would read in the bcc corpus frequency list as a dictionary, then having concatenated all the news/magazine articles as plain text, i would build a dictionary of all the words in the.
For seeing term levels, intended part of speech and sometimes. I would read in the bcc corpus frequency list as a dictionary, then having concatenated all the news/magazine articles as plain text, i would build a dictionary of all the words in the. The bcc corpus seems to have pretty loose licensing terms. Adding them meaningfully to dictionary definitions. The beijing language and culture university created a balanced corpus of 15 billion characters.
The Bcc Corpus Seems To Have Pretty Loose Licensing Terms.
For seeing term levels, intended part of speech and sometimes. The beijing language and culture university created a balanced corpus of 15 billion characters. Pleco already seems to be using frequency data to sort the search results. I've parsed out vocabulary from these taiwanese tests and converted to flashcards in pleco's format.
The Beijing Language And Culture University Created A Balanced Corpus Of 15 Billion Characters.
For corpora other than hkcancor, pycantonese provides the function read_chat () to read in cantonese. I would read in the bcc corpus frequency list as a dictionary, then having concatenated all the news/magazine articles as plain text, i would build a dictionary of all the words in the. Adding them meaningfully to dictionary definitions. The beijing language and culture university created a balanced corpus of 15 billion characters.